

gs://) image link and routes the image to a multimodal model. You can also supply the image using image or imageLink keys in each batch item. A JSON response is returned that contains a imageMetadata dictionary with a list of keywords, a list of subcategories, and a list of keywords synonyms. The metadata can be generated based on the image, the image title, and the categories.
This use case can be applied in the following ways:
- Enrich keywords for an image in a document.
- Generate SEO and alt text.
- Help with image-based product discovery.
- Enrich document indexing.
- Visually tag images for search and faceting.
- Expand synonyms for search recall.
- Auto-categorize images.
- Validate or correct categories.
- Increase semantic linking and recommendations.
Configure the LWAI Prediction image metadata enrichment use case
Configure the LWAI Prediction image metadata enrichment use case
Complete the steps to configure the image metadata enrichment use case that analyzes images to generate keywords, synonyms, and subcategories that enhance metadata content for image-based product discovery.The use case requires specific fields, parameters, and values be configured in the LWAI Prediction index pipeline stage, Field Mapping index pipeline stage, and Query Fields query pipeline stage to generate and display metadata for images.
Configure the LWAI Prediction index pipeline stage
- Sign in to Fusion and click Indexing > Index Pipelines. Click Add for a new pipeline and enter a Pipeline ID. For example, image-enrichment.
- Click Add a new pipeline stage and select LWAI Prediction.
- In the Label field, enter a unique identifier for this stage. For example, LWAI Image Metadata Enrichment.
-
In the Condition field, enter what the document must contain for the stage to select it. For example,
doc.hasField("image_url_t")means the document must have the image’s web address stored as a text field to be included in the stage. - In the Account Name field, select the Lucidworks AI API account name defined in Lucidworks AI Gateway.
-
In the Use Case field, select or enter
image-metadata-enrichmentfor the Lucidworks AI use case. -
In the Model field, you must enter a multi-modal model, which is required by the
image-metadata-enrichmentuse case. A multi-modal model can read images as well as text. -
In the Input context variable variable field, enter the name of the field that contains the image URL. For example,
<doc.image_url_t>. -
In the Destination field name and context output field, enter the name that will be used as both the field name in the document where the prediction is written and the context variable that contains the prediction. For example,
image_enrichment. -
In the Use Case Configuration section, you can add
useCaseConfigparameters and values to send to Lucidworks AI. These parameters give the model context, such as a title and categories, and set the maximum number of keywords, synonyms, and subcategories it returns. They are not filters: the stage enriches every document that meets its condition. To control which documents the stage processes, use the Condition field. The stage sends each value exactly as you enter it, with every request. It doesn’t replace<doc.field>templates in this section with values from the document, so enter fixed values that apply to every document the stage processes. Entercategoriesas a JSON array, such as["bathroom","kitchen","home","industrial"]. This example sends a title and a list of categories as context for the model, and setslocaletoen-USso the generated terms are in US English. It also limits the output to three keywords, five synonyms per keyword, and three subcategories.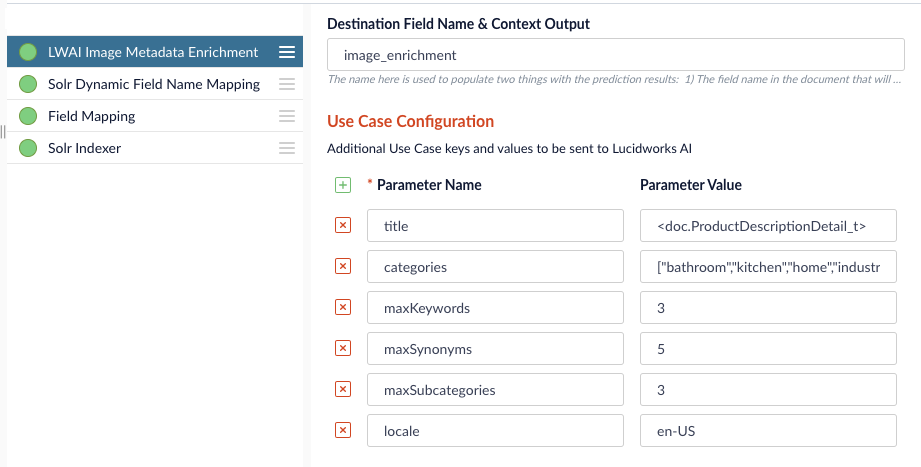
titlevalue is a<doc.ProductDescriptionDetail_t>template, which the stage sends as literal text. Replace it with a fixed value. -
In the Model Configuration section, you can add model parameters to send to Lucidworks AI, such as
temperatureormaxTokens. For Google Agent Platform models that use your own API key,googleRegionandgoogleProjectIdset the Google Cloud region and project where the model runs. - You can run this stage in two ways:
- Do not select the Call Asynchronously? checkbox to process this stage completely before proceeding with indexing. This is the same as using the Prediction API.
- Select the Call Asynchronously? checkbox to process predictions asynchronously without blocking the pipeline. This is the same thing as using the Async Prediction API, and is useful to process large documents without impacting further indexing processes.
- In the API Key field, enter the secret value specified in the external model.
- Click Save.
Configure the Field Mapping index pipeline stage
You may also need to set some parameters in the Field Mapping index pipeline stage.-
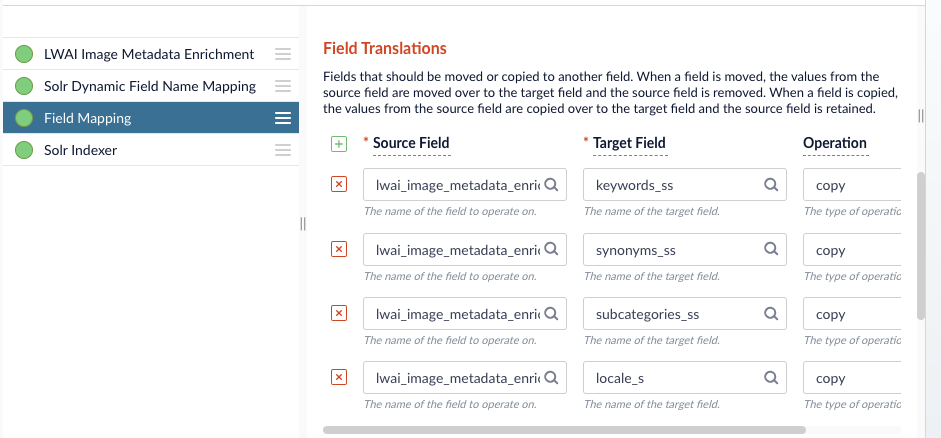
Click the Field Mapping stage and scroll to the Field Translations section.
For example, if the source field names are extremely long, you can use the Field Translations section to shorten them for your target index fields.
- When you enter all of the parameter and field values, click Save.
Set up a datasource
- Click Indexing > Datasources > Add.
-
Set up a datasource associated with the pipeline and connector.
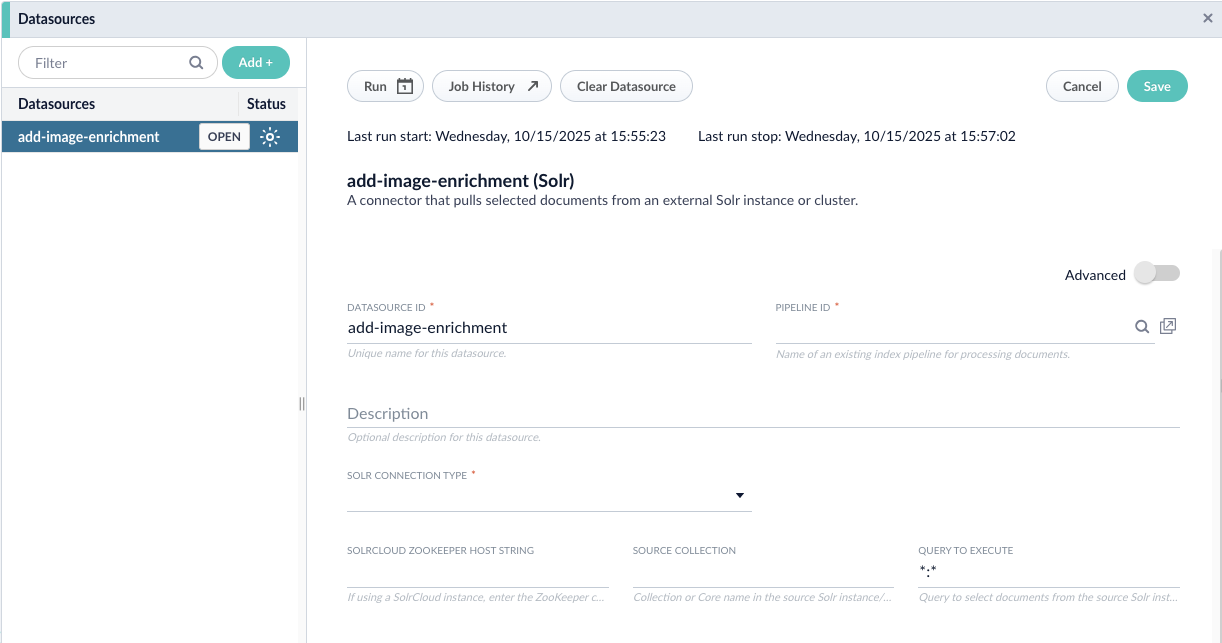
- Run the datasource to enrich the metadata for the images at the URL specified in the index pipeline.
Configure Query Fields stage
- Click Querying > Query Workbench and select the Query Fields stage.
-
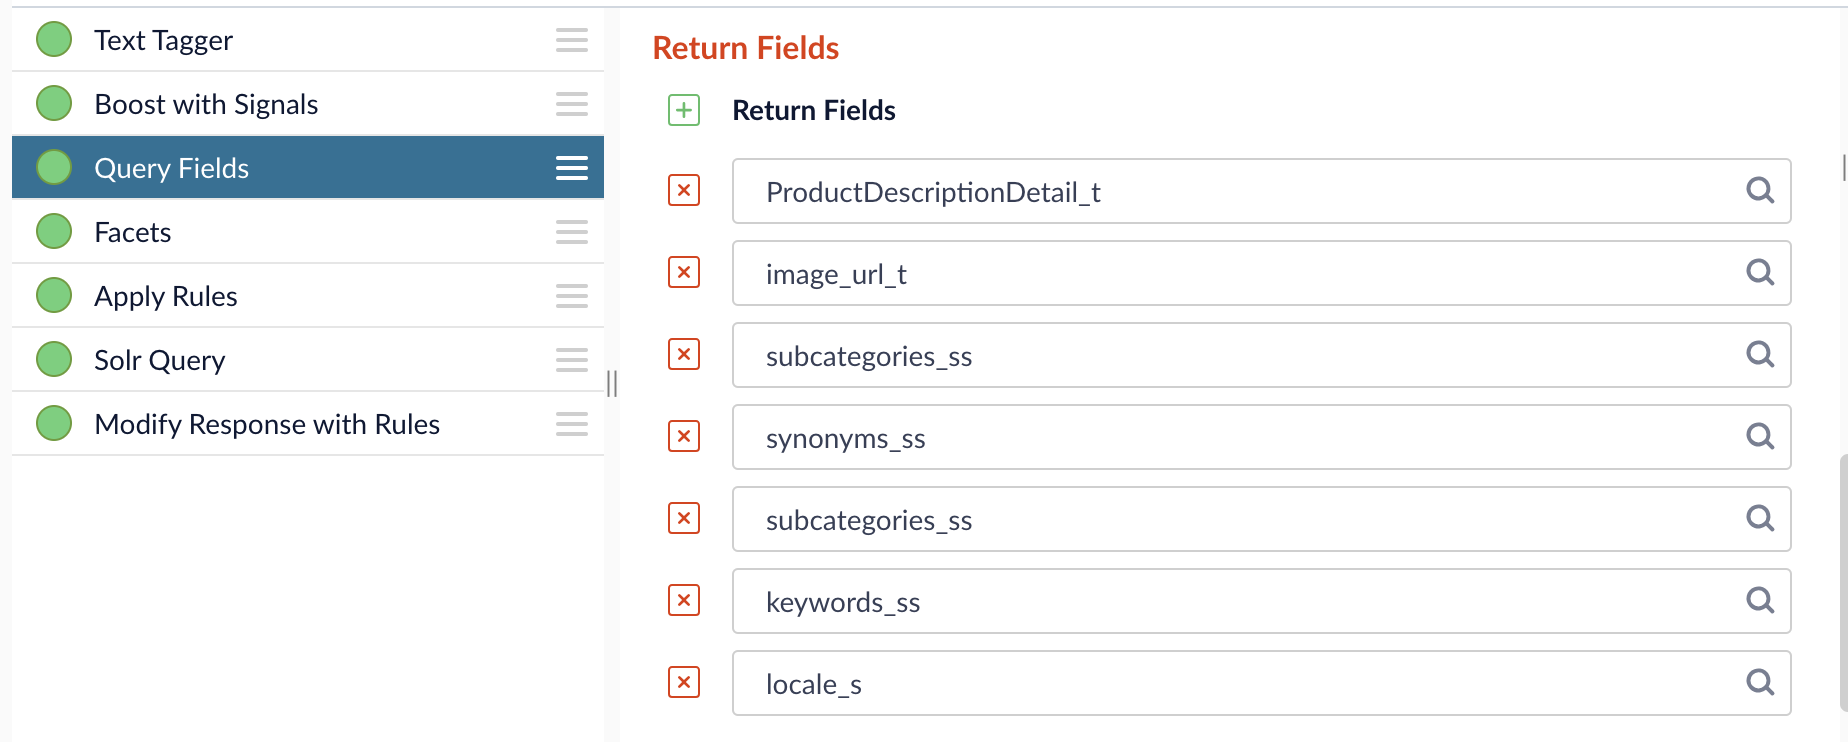
Scroll to the Return Fields section and enter the image metadata fields to include in the query results. The fields need to include, but do not have to be limited to, the fields specified in the indexing stage. This example includes the fields specified in indexing field example.
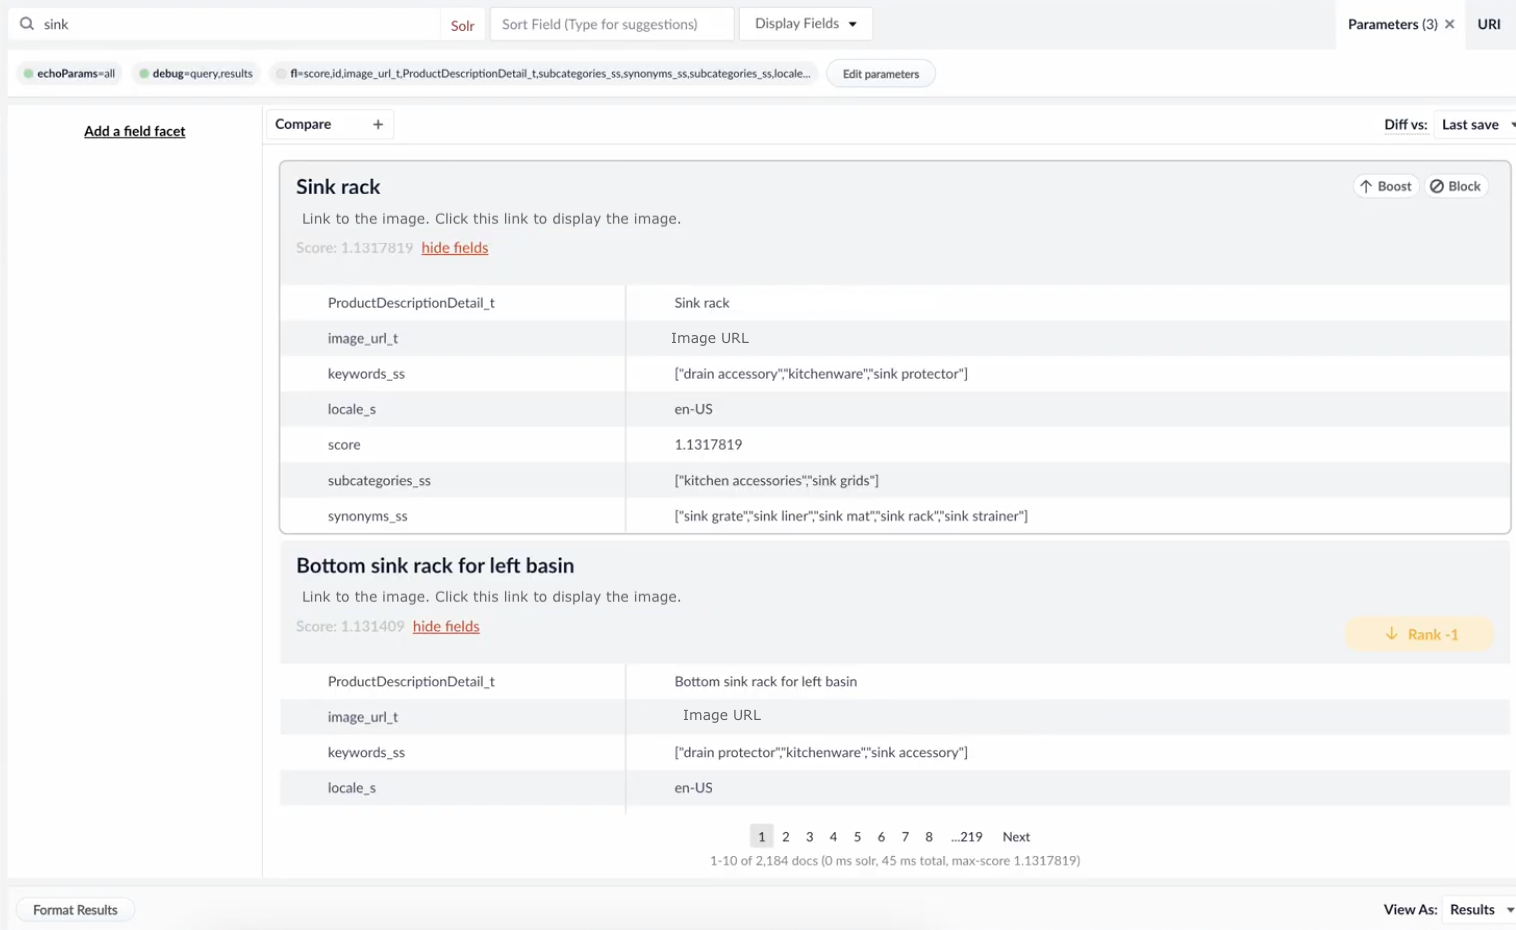
Review the query results
Review the results in the Query Workbench, which should include:- The image link under the title or the image URL to view the image.
-
The title, the locale of the generated terms (
en-USin this example), and the calculated score of the item. -
The keywords, subcategories, and synonyms generated for the image.
For this example, the categories sent were bathroom, kitchen, home, and industrial.
The model uses these categories as context for the subcategories it generates.
They don’t filter which documents are enriched.
Unique values for the image metadata enrichment use case
batch
batch
An array of request items. Each item is contained within curly brackets and accepts one of the following.
Freeform content contained in the document. Pass in either a base64-encoded image or an image link and it will be parsed to the correct field. This is meant to support Fusion specifically.
A field meant to take a string of a base64-encoded image. If included,
imageLink may not be included.useCaseConfig
useCaseConfig
Optional object to control metadata generation, such as what to consider and how much to return. The image must be provided in the
batch item as useCaseConfig only tunes the output.
These values are context for the model, not filters: every image in the request is enriched.This optional parameter is designated for the title of the image or other details to include for the generated items.
This optional parameter specifies the current categories for the item and is the basis for the subcategories generated.
This optional parameter has a default of
15 and specifies the maximum number of keywords the model should generate.This optional parameter has a default of
5 and specifies the maximum number of subcategories the model should generate.This optional parameter has a default of
5 and specifies the maximum number of synonyms the model should generate per keyword.Example requests
These examples show how to use the differentbatch parameters.